Flexible AI implementation through On-Premise and API Integration
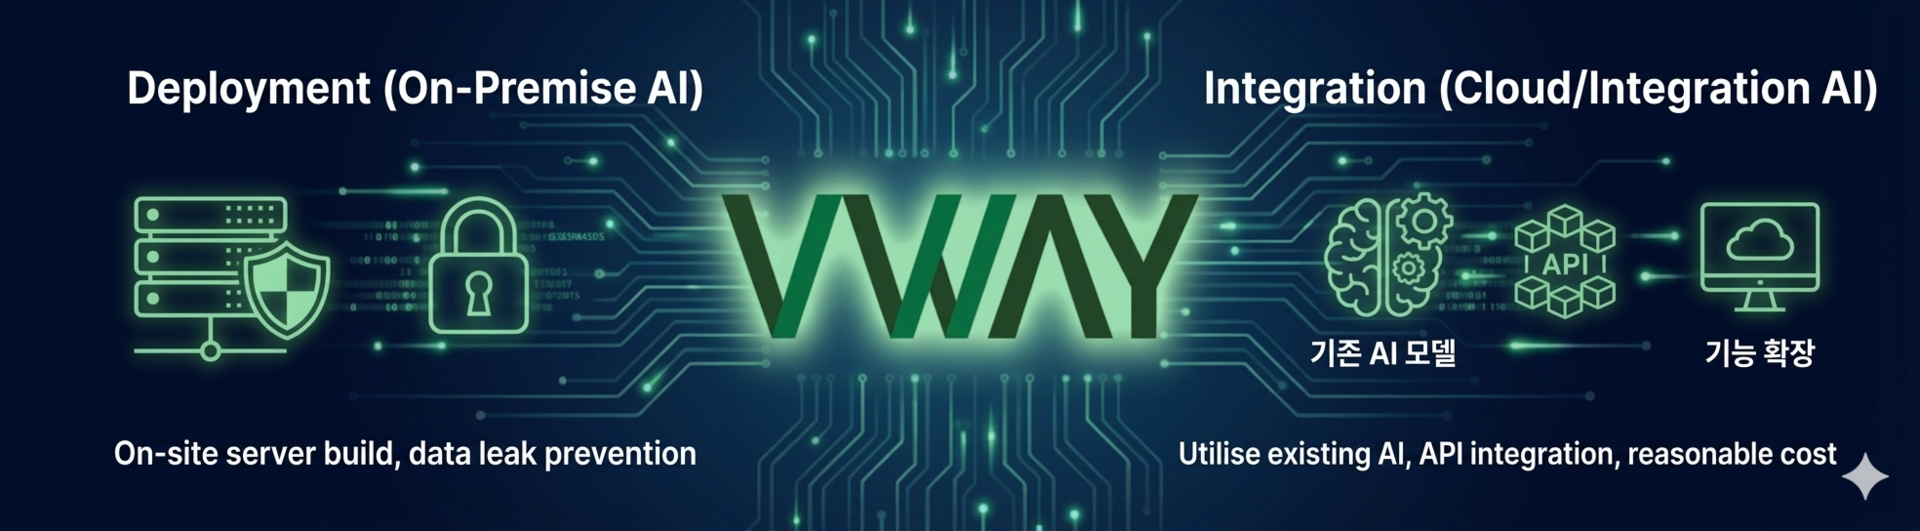
Zero Data Leakage: Custom-Built AI for Private Infrastructure
Optimized for high-security sectors like Defense, Automotive, and Semiconductors. This solution builds a dedicated sLLM (Small Large Language Model) based on verified open-source models within internal servers completely isolated from external networks.
1. Core Technology: Domain-Specific Fine-tuning
Standard AI often struggles with complex "Requirement Specifications" or "Legacy Code." VWAY fine-tunes proven open-source models using the client’s specific engineering data.
Result: Expert-level AI performance for specialized tasks such as Safety Analysis, Requirement Verification, Test Case Generation, and Code Review.
2. Accuracy Enhancement: RAG (Retrieval-Augmented Generation)
Hallucinations are critical failures in engineering. We implement a RAG architecture to ensure reliability.
Mechanism: Before generating a response, the AI retrieves relevant facts from the company’s technical repository (Vector DB).
Impact: Prevents "creative" errors by providing grounded answers, such as "According to page 34 of the reference manual..."
https://www.nvidia.com/en-us/glossary/retrieval-augmented-generation/
Resource Maximization: Fastest and Most Efficient Feature Expansion
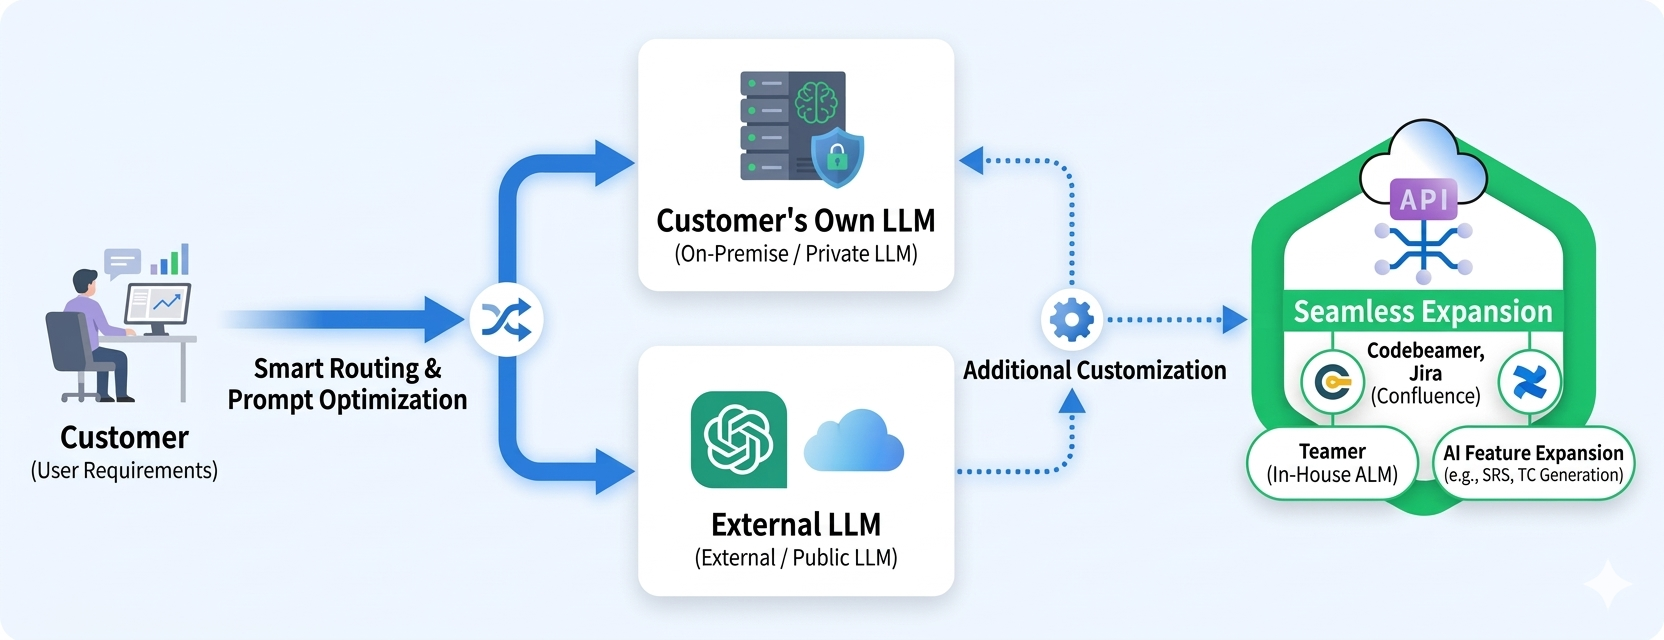
Designed for companies already utilizing high-performance models like GPT-4, Azure OpenAI, or Claude. Instead of building new models, VWAY connects its "Engineering Prompt Module" to the client's existing AI via API.
1. Balance of Cost-Efficiency and High Performance
Leverages existing AI infrastructure without the high CAPEX of model training or server builds. VWAY provides optimized prompt engineering and logic for SRS verification and automated testing in an API format.
2. Optimization Technology: Semantic Caching
We apply Semantic Caching to drastically reduce the latency and token costs inherent in API models.
Mechanism: User queries are converted into vectors and stored. If a semantically similar question (e.g., "Classify ASIL ratings per ISO 26262") is asked again, the system returns the cached answer instantly without calling the LLM.
Impact: Dramatically increases response speed and slashes unnecessary API call expenses.
Inquiry about
Service
Deployment Models
⦁ Required fields are marked.